How Many GPUs Do You Need to Serve a 70B Model?
On this page
Problem statement
"We want to self-host a 70B open model for our chat product. How many GPUs do we need?"
A capacity question in disguise. The interviewer wants to see you turn a vague request into memory and throughput arithmetic, state your assumptions, and say how you would confirm the number.
Why it happens
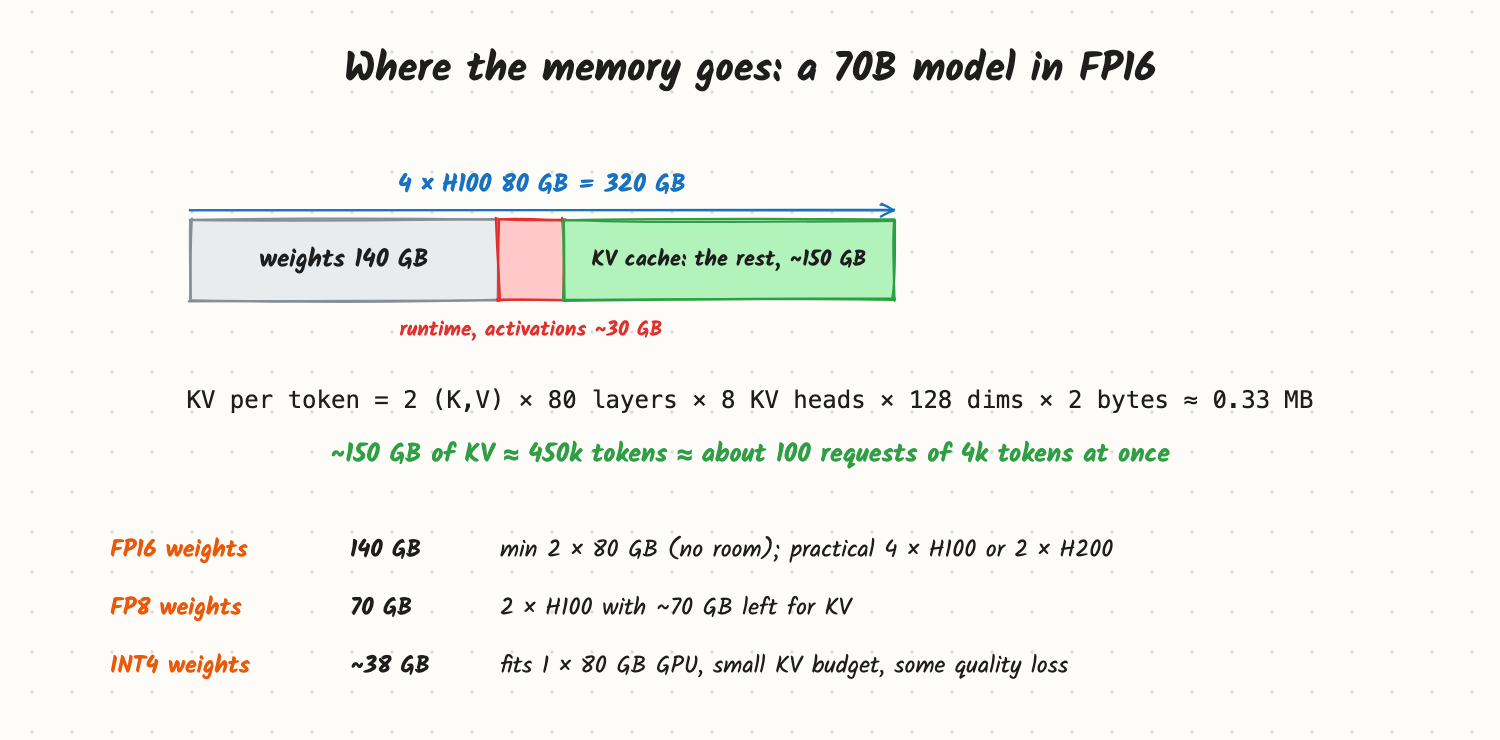
- Weights are fixed: parameters × bytes per parameter. 140 GB in FP16 or BF16, 70 GB in FP8 or INT8, about 35–40 GB in 4-bit.
- The KV cache grows with traffic: 2 (keys and values) × layers × KV heads × head size × bytes. For a typical 70B shape (80 layers, 8 KV heads, 128 dimensions) that is about 0.33 MB per token in FP16, so one 4,000-token conversation holds about 1.3 GB.
- Prefill and decode stress different things: prefill (reading the prompt) is compute-bound; decode (writing the answer one token at a time) is memory-bandwidth-bound, because every step reads all the weights.
- Real systems never run at 100%: traffic is bursty, and queueing makes latency explode as utilisation approaches the limit.
Try it yourself first
You have the full problem. Sketch your answer, then sign up free to read the complete walkthrough.
- The complete design, flow by flow, with pictures
- Deep dives into the hard parts
- What mid, senior and staff candidates are expected to say
- Full company question lists
Free forever. No card needed.