Web Crawler Multithreaded
On this page
Problem statement
Write a crawler that, starting from one URL, returns every page reachable on the same host. You are given
getUrls(url), which downloads a page and returns the links on it. It is slow (a network call of about 200 ms) but safe to call from several threads at once. Follow only links whose host matches the start URL's host, and fetch each page at most once.
Part 1: make it correct, single-threaded. Part 2: make it fast by fetching many pages at the same time. Expect follow-ups on limits, failures and politeness.
This is a concurrency round dressed up as graph traversal: part 1 is a plain BFS, and part 2 is where the interview really happens. The single-threaded and multithreaded versions on LeetCode are 1236 and 1242.
Example
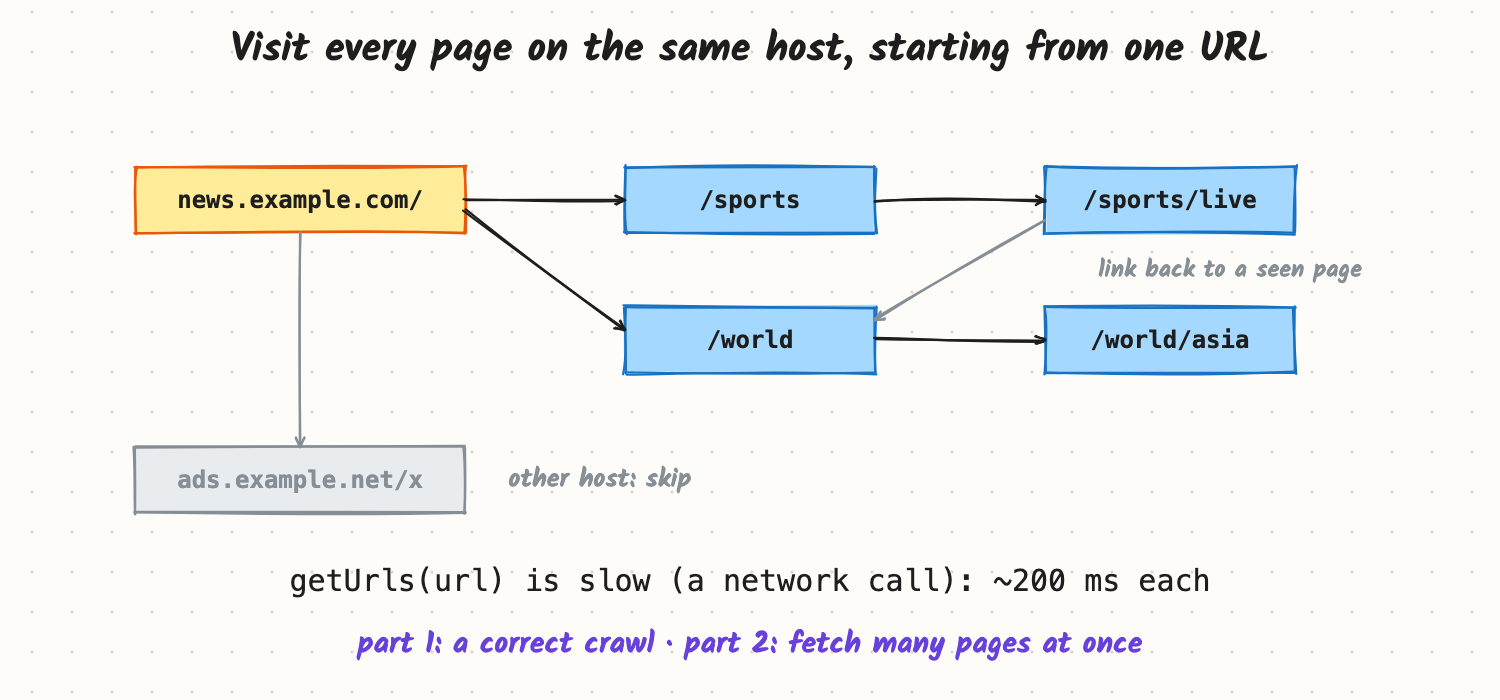
start = http://news.example.com/
/              -> /sports, /world, http://ads.example.net/x
/sports        -> /sports/live
/sports/live   -> /world
/world         -> /world/asia, /

Output (any order): /, /sports, /world, /sports/live, /world/asia   (on news.example.com)
Constraints (assumed)
- Up to 1,000 pages per host; each
getUrlscall takes about 200 ms. - URLs are already normalized (no fragments, consistent trailing slashes). Same host means an exact hostname match.
What this question tests
- Seeing the crawl as BFS on a graph with a visited set.
- Knowing that the wait is I/O, so threads help even in Python.
- Avoiding races on shared state and knowing when the crawl is finished.
Questions to ask first
- What counts as the same host? Is
www.a different host? Do ports matter? (Here: exact hostname match.) - Is
getUrlsthread-safe? (Here: yes.) - Is there a limit on concurrent requests to the site? (Assume a pool of 8–16 workers.)
- Does the output order matter? (Here: no.)
- What should happen if a fetch fails? (Part 1: skip it. Retries are a follow-up.)
Try it yourself first
You have the full problem. Sketch your answer, then sign up free to read the complete walkthrough.
- The complete design, flow by flow, with pictures
- Deep dives into the hard parts
- What mid, senior and staff candidates are expected to say
- Full company question lists
Free forever. No card needed.