Design Facebook News Feed Ranking
On this page
Problem Description
In this interview, we're going to design the ranking behind a social network's home feed, similar to the Facebook News Feed or the LinkedIn feed. People follow friends, groups and pages, and together these post far more than anyone can read. When someone opens the app, the system decides which posts from their friends, groups and pages to show and in what order, so the posts they'll care about most come first, and it shows more as they scroll. Posts that break the site's rules never appear, and borderline ones are shown less. People like, comment on, share, hide or report the posts they see, and the system keeps learning from what they do. You can use existing building blocks: a posts service that stores every post and knows who follows whom, and a content classifier that labels each post as fine, borderline or violating. This interview is about choosing and ordering posts, not about storing them or sending them to followers.
Not the same as Design FB News Feed, which is about storing posts and delivering them to followers' feeds.
Out of Scope
- Suggested posts from accounts the user doesn't follow – they need their own search over all posts; a good follow-up question.
- Ads in the feed – placed by the ads system in slots we leave for it.
- Storing posts and the follow graph – the posts service already does this.
- Training the content classifier – a separate system; we only use its labels.
- Comment ranking, notifications and search – other products with their own ranking.
Good Clarifying Questions
- How many people, and how many posts could each feed choose from? – About 1 billion daily users who open the feed about 10 times a day. At each open there are about 1,500 posts from the last two days that the user hasn't seen yet.
- What does "care about most" mean for the business? – People having real conversations with friends and communities, and coming back. Time spent alone isn't the goal, and hides and reports must not go up.
- How fast must the feed load? – The first page within 300 ms at p99, of which about 100 ms can go to the models. Later pages, as the user scrolls, within 150 ms.
- How fresh must it be? – A new post can appear within a minute. A post that is suddenly getting lots of comments should move up within about 5 minutes. The model should be retrained at least daily.
- What if ranking fails? – The feed must still load, even if less well ordered; an error page is not acceptable.
Requirements
Functional Requirements
- Show a Ranked Feed – When a user opens the app, the feed shows posts from their friends, groups and pages, the ones they'll care about most first, and more as they scroll.
- Keep Rule-Breaking Posts Out – The feed never shows posts labelled violating and shows borderline posts lower.
- Record What Users Do – The system records which posts each user saw, where in the feed, and what they did with them: like, comment, share, hide, report, or how long they looked.
- Keep Learning – The system trains a new model from these records at least daily and gives it to users only after it proves at least as good as the current one.
Non-Functional Requirements
- Scale – 1B daily users × 10 opens = 10B feed requests a day: about 115K/s on average, 300K/s at peak, each choosing from about 1,500 posts.
- Latency – First page under 300 ms at p99, with about 100 ms for the models; later pages under 150 ms.
- Freshness – A new post can appear within 1 minute; a post's new likes and comments affect its ranking within 5 minutes; a new model at least daily.
- Availability – 99.9%. If the models or the feature store are down, the feed still loads in a simpler order; never an error.
Problem Framing
ML objective – The business goal is that people have real conversations with friends and communities and come back. The model takes one (user, post) pair at the moment of the request and predicts the probability of six actions: like, comment, share, a long view (on screen for 10 seconds or more), hide and report. The feed is sorted by one value score, the six probabilities times fixed weights, added up: comments and shares count most, likes and long views a little, hides and reports strongly against (for example comment 5, share 4, like 1, long view 1, hide −20, report −50). Predicting several actions, including the bad ones, is what keeps "Like if you agree!" bait from winning on likes alone.
Label – Each label is the user's own action on that post within 24 hours of seeing it, taken from the app's events: 1 if they did it, 0 if not. Labels therefore arrive up to a day late. Their known biases: users only act on posts we chose to show them, and posts near the top get more actions just for being there (position bias).
Offline metrics – Log loss for each of the six actions, on the most recent day of data, which the model never trained on. Log loss checks that a predicted 10% really happens about 10% of the time; that matters here because the value score multiplies probabilities by weights, so a probability must be right in size, not only in order (which is all AUC checks).
Online metrics – An A/B test decides each launch on meaningful interactions per daily user (comments and shares between people). Guardrails: hides and reports per 1,000 posts seen must not rise, and daily active users must not fall.
Data and Features
Training data – One row per post a user actually saw: about 20 posts per feed open, so about 200B rows a day. The row's six labels come from joining that user's actions on that post within 24 hours. Events come from two places: the Feed Service records which posts it served and where, and the app reports what the user did.
Features, grouped by what they describe:
| Group | Features | Computed |
|---|---|---|
| User | How active they are, how often they comment rather than like, which post types they engage with (photo, video, link, text) | Daily |
| Post | Type, age, who posted it (friend, group or page), the classifier's label | Age at request time; the rest when the post is created |
| Post engagement | Likes, comments and shares so far; the author's average engagement per post | Daily |
| User × author | How often the user commented on, liked or messaged this author in the last 30 days; groups they share | Daily |
| Context | Time of day, device, connection speed | At request time |
User × author interactions are usually the strongest signal: people care most about posts from the people they actually talk to.
API Design
REST over HTTPS with JSON.
Get the Feed
The first call ranks a new feed; calls with a cursor return the next page of the same ranking.
GET /v1/feed?limit=10
GET /v1/feed?cursor=c_9f2&limit=10            # next page

→ Response:
{
  "requestId": "r_7731",                      # ties later events to this ranking
  "posts": [
    { "postId": "p_5512", "position": 1 },
    { "postId": "p_0418", "position": 2 }
  ],
  "nextCursor": "c_9f2"
}
Record Actions
The app sends what the user did, in batches every few seconds.
POST /v1/events
{
  "requestId": "r_7731",
  "events": [
    { "postId": "p_5512", "action": "view", "seconds": 14 },
    { "postId": "p_5512", "action": "comment", "at": "2026-11-16T07:55:12Z" },
    { "postId": "p_0418", "action": "hide", "at": "2026-11-16T07:55:40Z" }
  ]
}

→ Response: 202 Accepted- The user is identified by the login token in the
Authorizationheader, never by the body. - The app loads each post's content with the posts service's existing call; the feed only decides which posts and in what order.
- Keep Rule-Breaking Posts Out has no endpoint: it removes or lowers posts inside Get the Feed.
- Keep Learning has no endpoint: it is background work, and its only visible effect is a better order in Get the Feed.
High-Level Design
One requirement at a time, in the simplest way that works; the deep dives then make it meet the numbers.
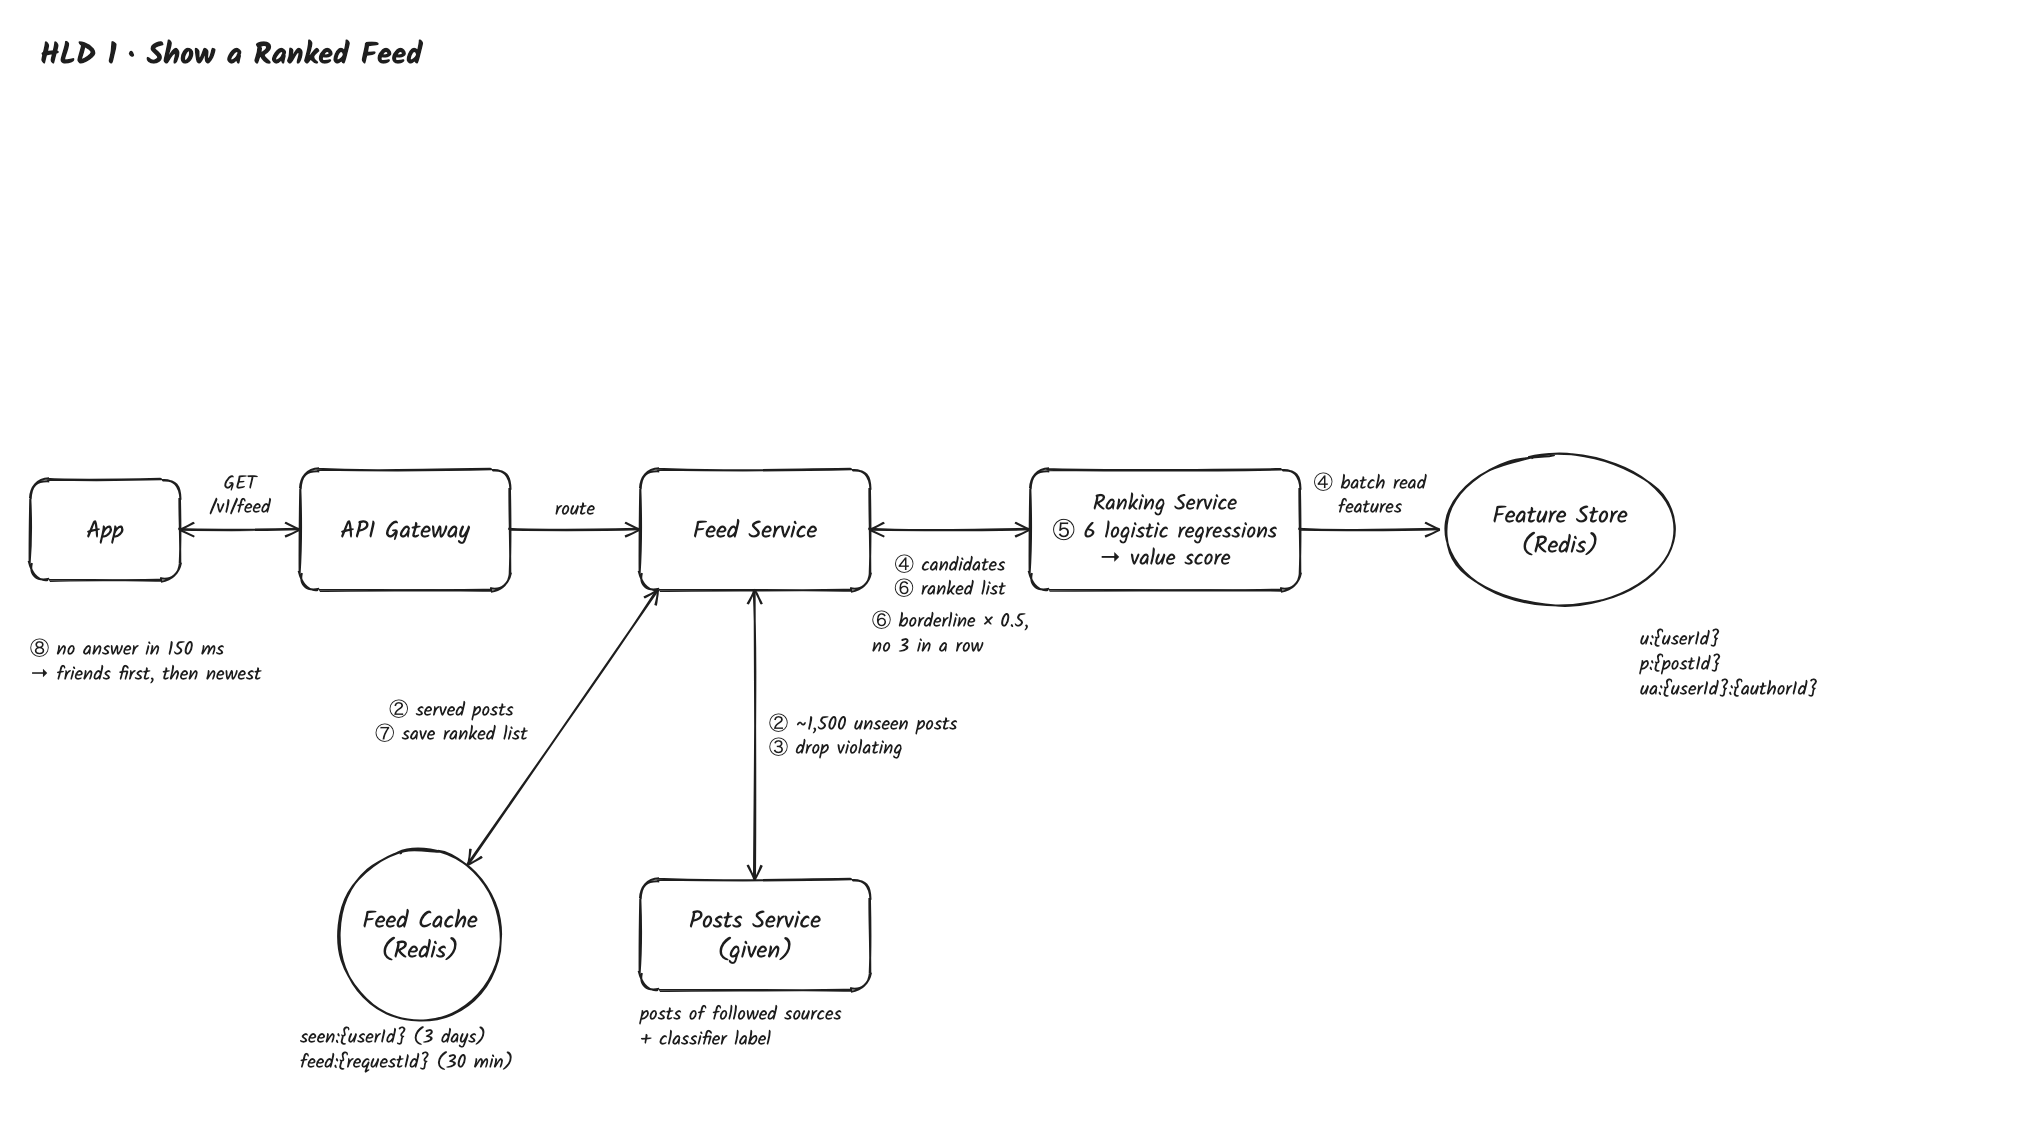
1. Show a Ranked Feed
Path: App → API Gateway → Feed Service → Posts Service → Ranking Service → Feature Store → back to the App
- The app calls
GET /v1/feed. The API Gateway checks the login token, routes the call to the Feed Service and spreads calls across its servers, skipping one that fails its health check. Feed Service servers keep nothing in memory, so any server can handle any call. - The Feed Service reads the posts this user was already served from the Feed Cache, Redis (
seen:{userId}, a set kept for 3 days), then asks the Posts Service for posts from the last 2 days by the user's friends, groups and pages, minus those: about 1,500 candidates. Because posts are read at request time, a new post can appear at the user's very next open (NFR 3). - Keep Rule-Breaking Posts Out, part 1: the Feed Service drops every candidate whose classifier label, stored with the post in the Posts Service, is violating.
- The Feed Service sends the candidates to the Ranking Service, which reads their features in one batch call from the Feature Store, Redis (a hash per user
u:{userId}, per postp:{postId}, and per user and authorua:{userId}:{authorId}). Redis, because one request reads features for 1,500 posts within a few milliseconds. - The Ranking Service scores each post with the baseline: one logistic regression per action, six small models whose probabilities are combined into the value score. It's the baseline because it trains in hours on billions of rows, scores 1,500 posts in a few milliseconds of CPU, and its weights are easy to read, so we have a working feed in week one.
- Keep Rule-Breaking Posts Out, part 2: the Ranking Service halves the score of borderline posts, sorts by score, and moves a post down if it would be the third in a row from the same group or page.
- The Feed Service saves the ranked list in the Feed Cache (
feed:{requestId}, 30 minutes), returns the first 10 with anextCursor, and adds them toseen:{userId}. A call with a cursor reads the next 10 from that list without ranking again, well within 150 ms (NFR 2). - If the Ranking Service doesn't answer within 150 ms, or the Feature Store is down, the Feed Service orders the candidates itself, friends first and then newest, so the feed still loads (NFR 4).
2. Record What Users Do
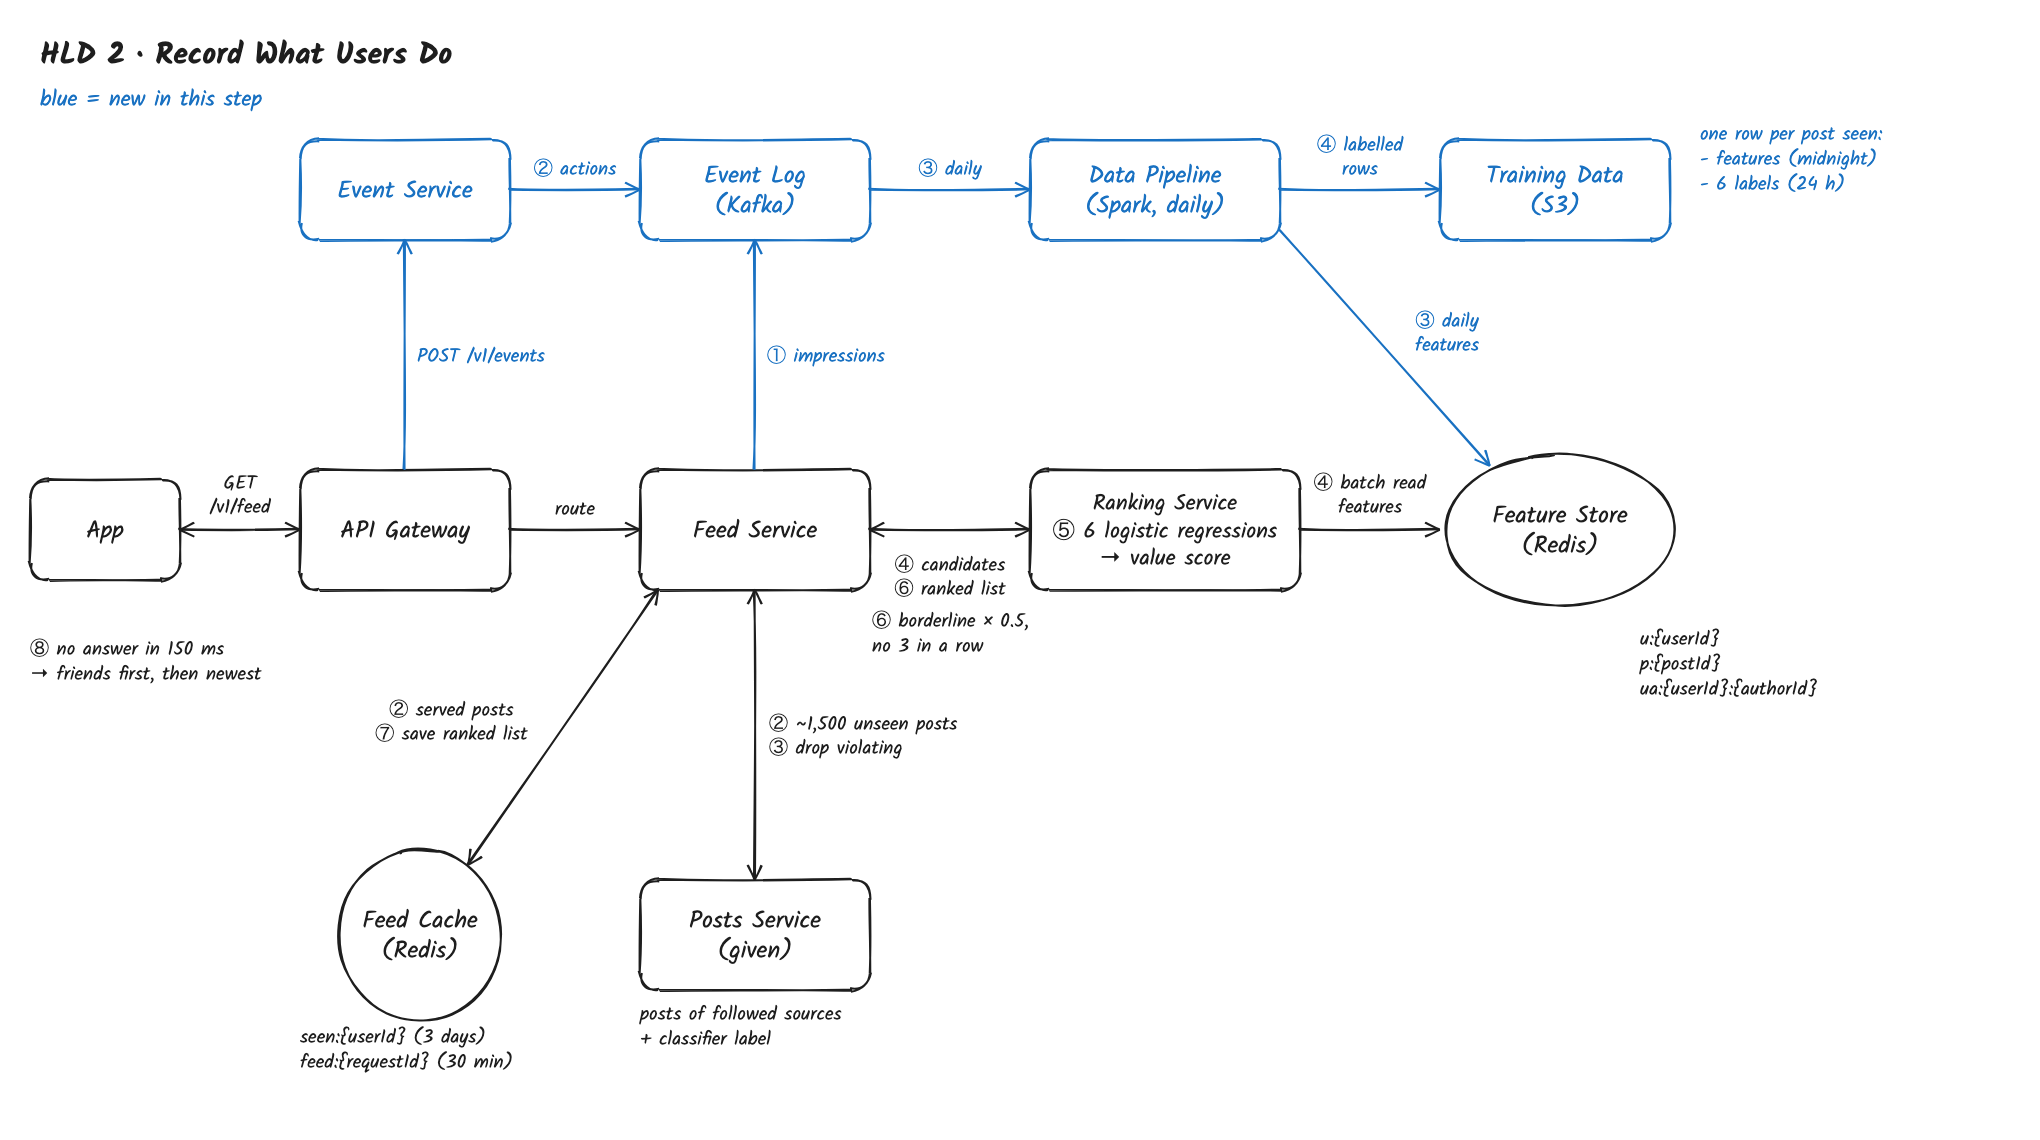
Path: Feed Service → Event Log; App → API Gateway → Event Service → Event Log → Data Pipeline → Feature Store and Training Data
- When the Feed Service returns a page, it writes one impression event per post to the Event Log, Kafka:
requestId,userId,postId,position,modelVersion, time. Kafka, because the events are an append-only stream that several jobs read at their own pace; it keeps them for 7 days. - The app sends what the user did with
POST /v1/events. The API Gateway routes it to the Event Service, which checks the events and writes them to the Event Log. Aviewevent, with its seconds on screen, is sent once a post has actually been on screen, so a post the user never scrolled to doesn't count as seen. - Once a day, the Data Pipeline, a Spark job, reads the day's events from the Event Log and computes the daily features in the table above (user, post engagement, user × author). It loads them into the Feature Store for serving.
- The Data Pipeline then builds training rows: for each impression with a
viewevent, it collects that user's actions on that post within 24 hours into six labels, adds the features it just computed, and writes the rows to Training Data, S3 (Parquet files, one folder per day). Files in S3, because training reads billions of rows in large scans and never updates one.
3. Keep Learning
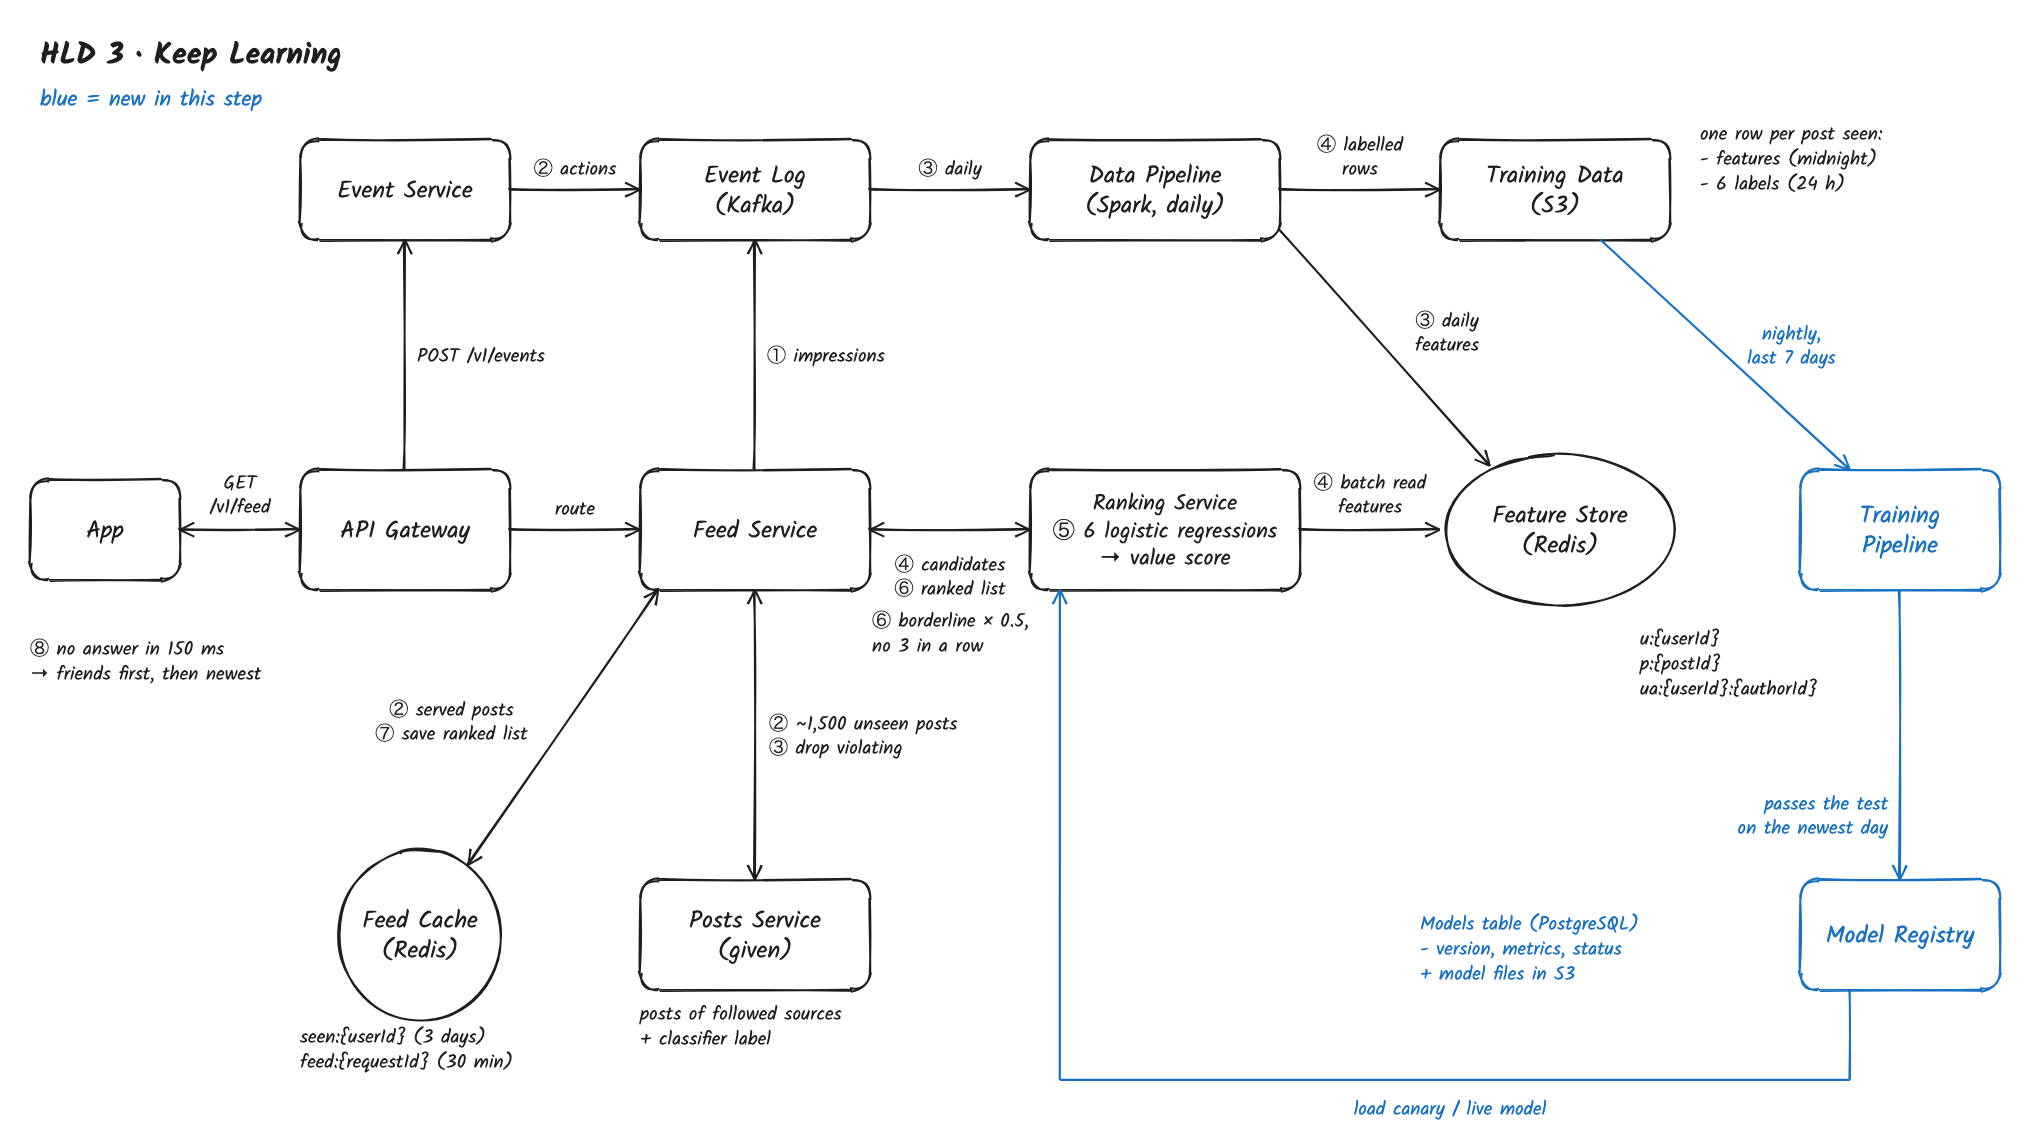
Path: Training Data → Training Pipeline → Model Registry → Ranking Service
- Each night, the Training Pipeline trains the six models on the last 7 days of rows from Training Data.
- It then tests them on the most recent day, which they didn't train on. Splitting by time makes the test look like tomorrow, the day the model will actually serve. The new models pass only if log loss for every action is no worse than the live models', overall and for new users and each region.
- A model that passes is saved in the Model Registry: its files in S3, plus a row in the Models table in PostgreSQL (
version,metrics,status: candidate, canary, live or retired). - Ranking Service servers check the Models table every minute. A canary model serves 1% of users, chosen by a hash of
userId; every impression already carries itsmodelVersion(flow 2), so its guardrails can be compared with the live model's within hours, and then it becomes live. A new model design (new features or a new kind of model) instead runs as a full A/B test on meaningful interactions for one to two weeks. - Rolling back is setting the previous version back to live; every server loads it within a minute.
Known Gaps So Far – this design works for a small network, but not yet for our requirements:
- The model is too simple, and a better one doesn't fit the budget. Six separate logistic regressions can't learn from the user's recent history or from combinations of signals, but a model that can costs about 100 times more per post, and scoring all 1,500 candidates with it is 450M posts a second at peak, past the models' 100 ms (NFR 1, NFR 2).
- Engagement features are up to a day old. A post getting 40 comments from the user's family this hour looks like a post with none until tomorrow, and a page the user hid this morning still ranks as before (NFR 3).
- Training doesn't see what serving saw. Training rows get the features computed at midnight, not the ones served at 8:00; posts at the top get more actions just for being at the top, so the model learns its own order; and about 95% of 200B rows a day have no action at all (Label, FR 4).
Deep Dives
Three deep dives, one per gap: the ranking budget first because it's the bottleneck, then freshness, then the training data.
1. How do we score 1,500 posts with a strong model, 300,000 times a second, within 100 ms?
The problem: the baseline treats the six actions separately and only sees hand-made features, so it can't tell a lively conversation among close friends from a busy group's 60th post of the day. A model that can costs about 100 times more per post; on all 1,500 candidates that is 450M posts a second at peak, which needs thousands of GPU servers and runs past the 100 ms for models (NFR 1, NFR 2).
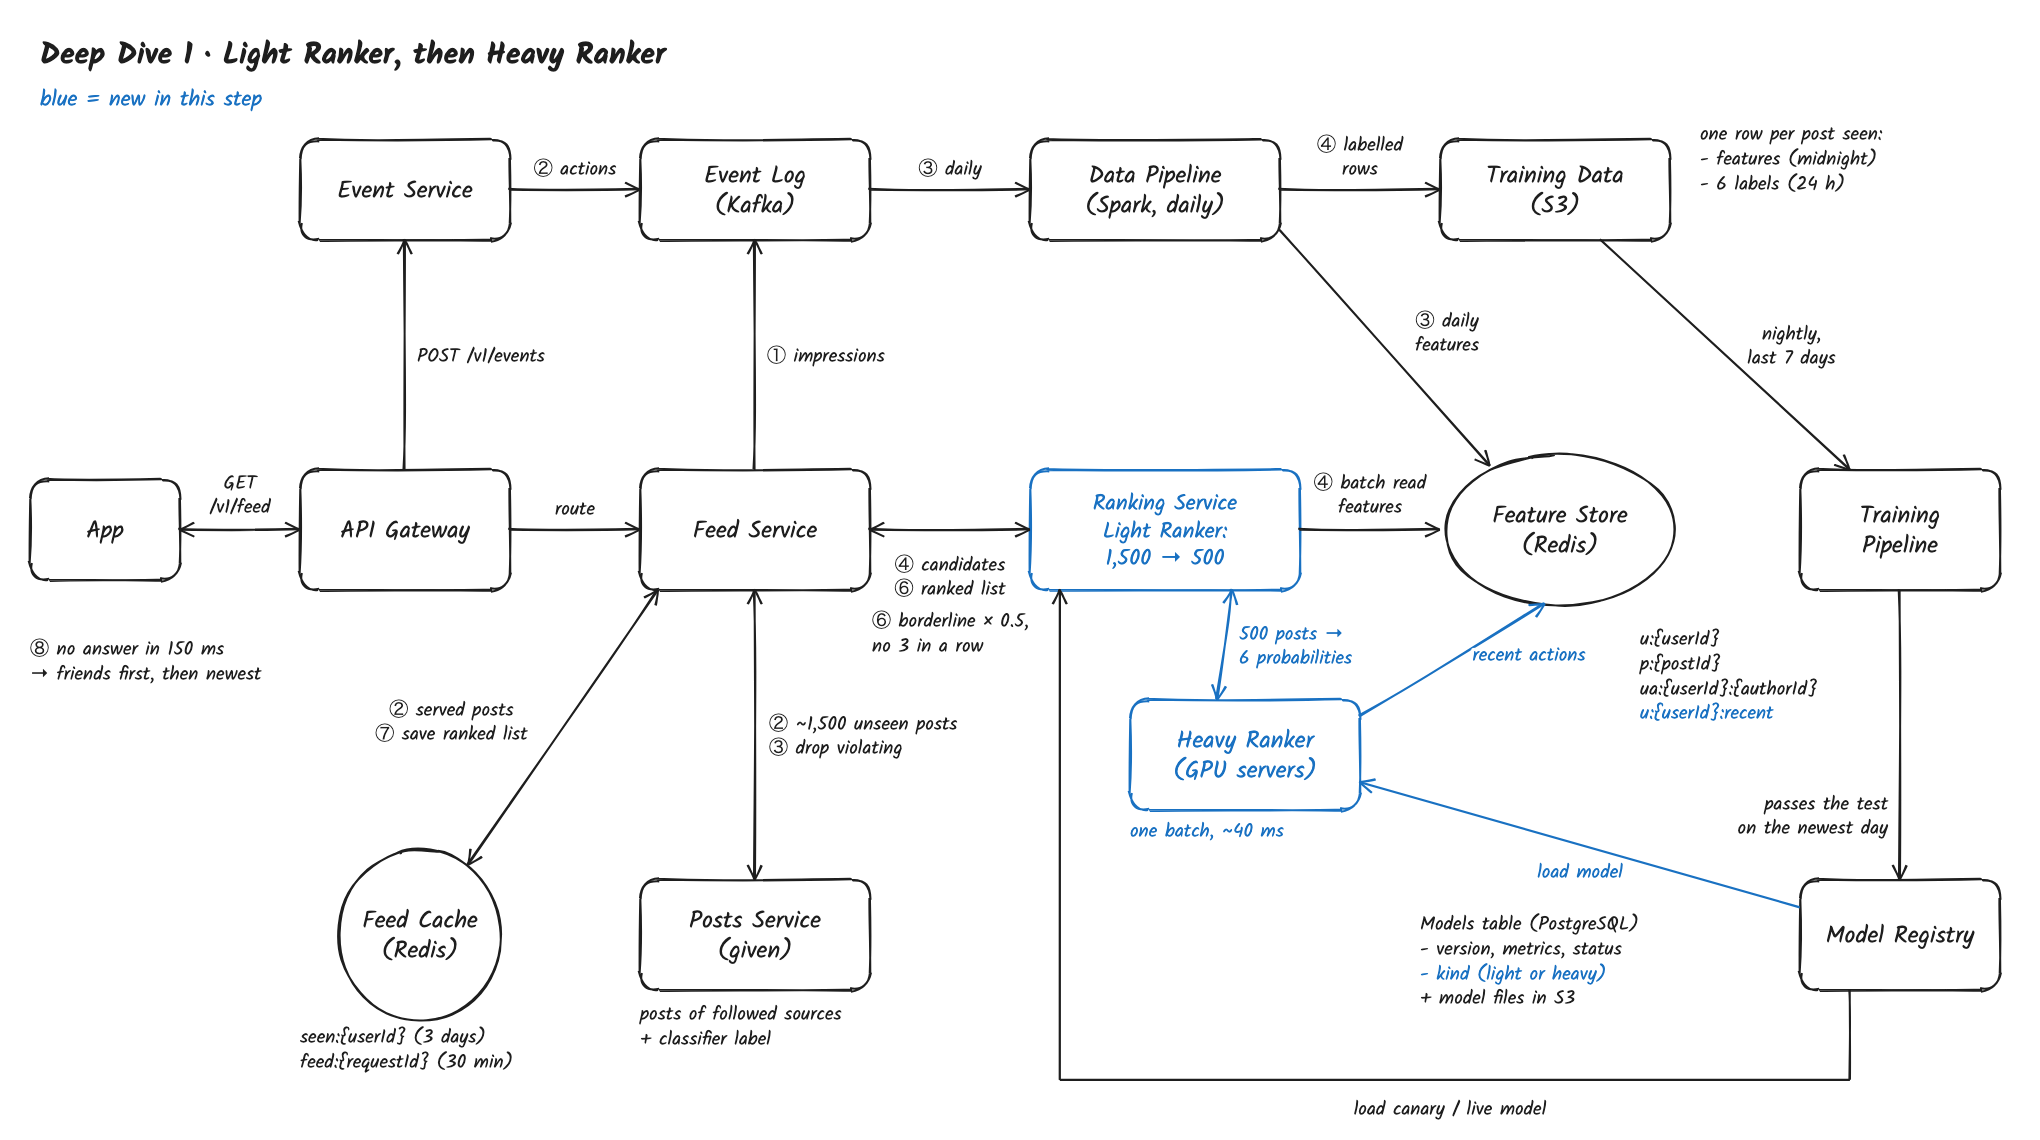
Solution: Rank in two stages – the Ranking Service's Light Ranker scores all 1,500 candidates with the cheap baseline and keeps the top 500, then the Heavy Ranker, a multi-task neural network on GPU servers, predicts all six actions for those 500 in one batch, so the feed gets a strong model within 100 ms at a third of the cost.
A multi-task model is one neural network with shared layers and one small output ("head") per action. The shared layers learn from all six actions at once, so rare actions such as shares and reports learn from the plentiful likes and views, and one call returns all six probabilities.
- Light Ranker: the Ranking Service keeps flow 1's six logistic regressions on about 20 cheap features. It scores all 1,500 candidates in about 2 ms of CPU and keeps the 500 with the highest value score.
- Heavy features: for those 500, the Ranking Service reads what the baseline couldn't use from the Feature Store: the user's last 50 actions (which authors and groups they commented on or hid), kept as a list
u:{userId}:recent. The Heavy Ranker learns its own embeddings (lists of numbers that place similar authors, groups and post types close together) for every author, group and post type, so it can tell that this user comments on family posts and skips memes. - Heavy Ranker: a separate service on GPU servers, which the Ranking Service calls once per request with all 500 posts. One batched call takes about 40 ms. Cost: 300K requests a second × 500 posts = 150M posts a second; at about 100K posts a second per GPU server, that's about 1,500 servers. Scoring all 1,500 candidates would need about 4,500.
- Calibration: after training, each head gets a small correction fitted on the newest day, so a predicted 10% really means 10%. Without it, the value score's weights would mix numbers of different scales.
- Value weights: the weights from Problem Framing stay fixed in the Models table and change only through an A/B test on meaningful interactions, never with each nightly model.
- Budget: Posts Service about 50 ms, Light Ranker and feature reads about 20 ms, Heavy Ranker about 40 ms, rules and saving about 10 ms: about 120 ms typical, which leaves room for the 300 ms p99. If the Heavy Ranker doesn't answer within 80 ms, the Ranking Service returns the Light Ranker's order, which is better than flow 1's friends-then-newest fallback.
- Checking the Light Ranker: for 0.1% of requests the Heavy Ranker also scores all 1,500 candidates, and we track how many of its top 50 the Light Ranker kept (target: at least 95%).
- Both rankers are trained nightly by the Training Pipeline and saved in the Model Registry with a
kind(light or heavy); the Heavy Ranker loads its version the same way the Ranking Service does.
Other options:
- The Heavy Ranker on all 1,500 – the simplest, but about 4,500 GPU servers instead of 1,500, and three times longer batches in the 100 ms budget.
- Gradient-boosted trees as the strong model – very good with counts and ratios, but one model per action, and weak at learning from a user's sequence of recent actions or from millions of author IDs.
- Two-tower embeddings with nearest-neighbour search – the standard way to find candidates among millions of items; here the candidates are already a small set from the user's own friends, groups and pages, so it solves a problem we don't have (it matters for suggested posts, which are out of scope).
Trade-off: two models to train, test and keep in step, and a post the Light Ranker drops never gets a second look.
What changed: step 5 of flow 1 now runs the Light Ranker and then the Heavy Ranker; the GPU servers and the user's recent-actions list are new; Model Registry rows get a kind. NFR 1 and NFR 2 are met.
2. How does a post that's taking off right now move up within 5 minutes?
The problem: engagement counts come only from the daily Data Pipeline, so a post's likes and comments since midnight are invisible to the ranker, and so is what the user did a minute ago. A sister's engagement post with 40 comments in the last hour ranks like a post with none (NFR 3: 5 minutes).
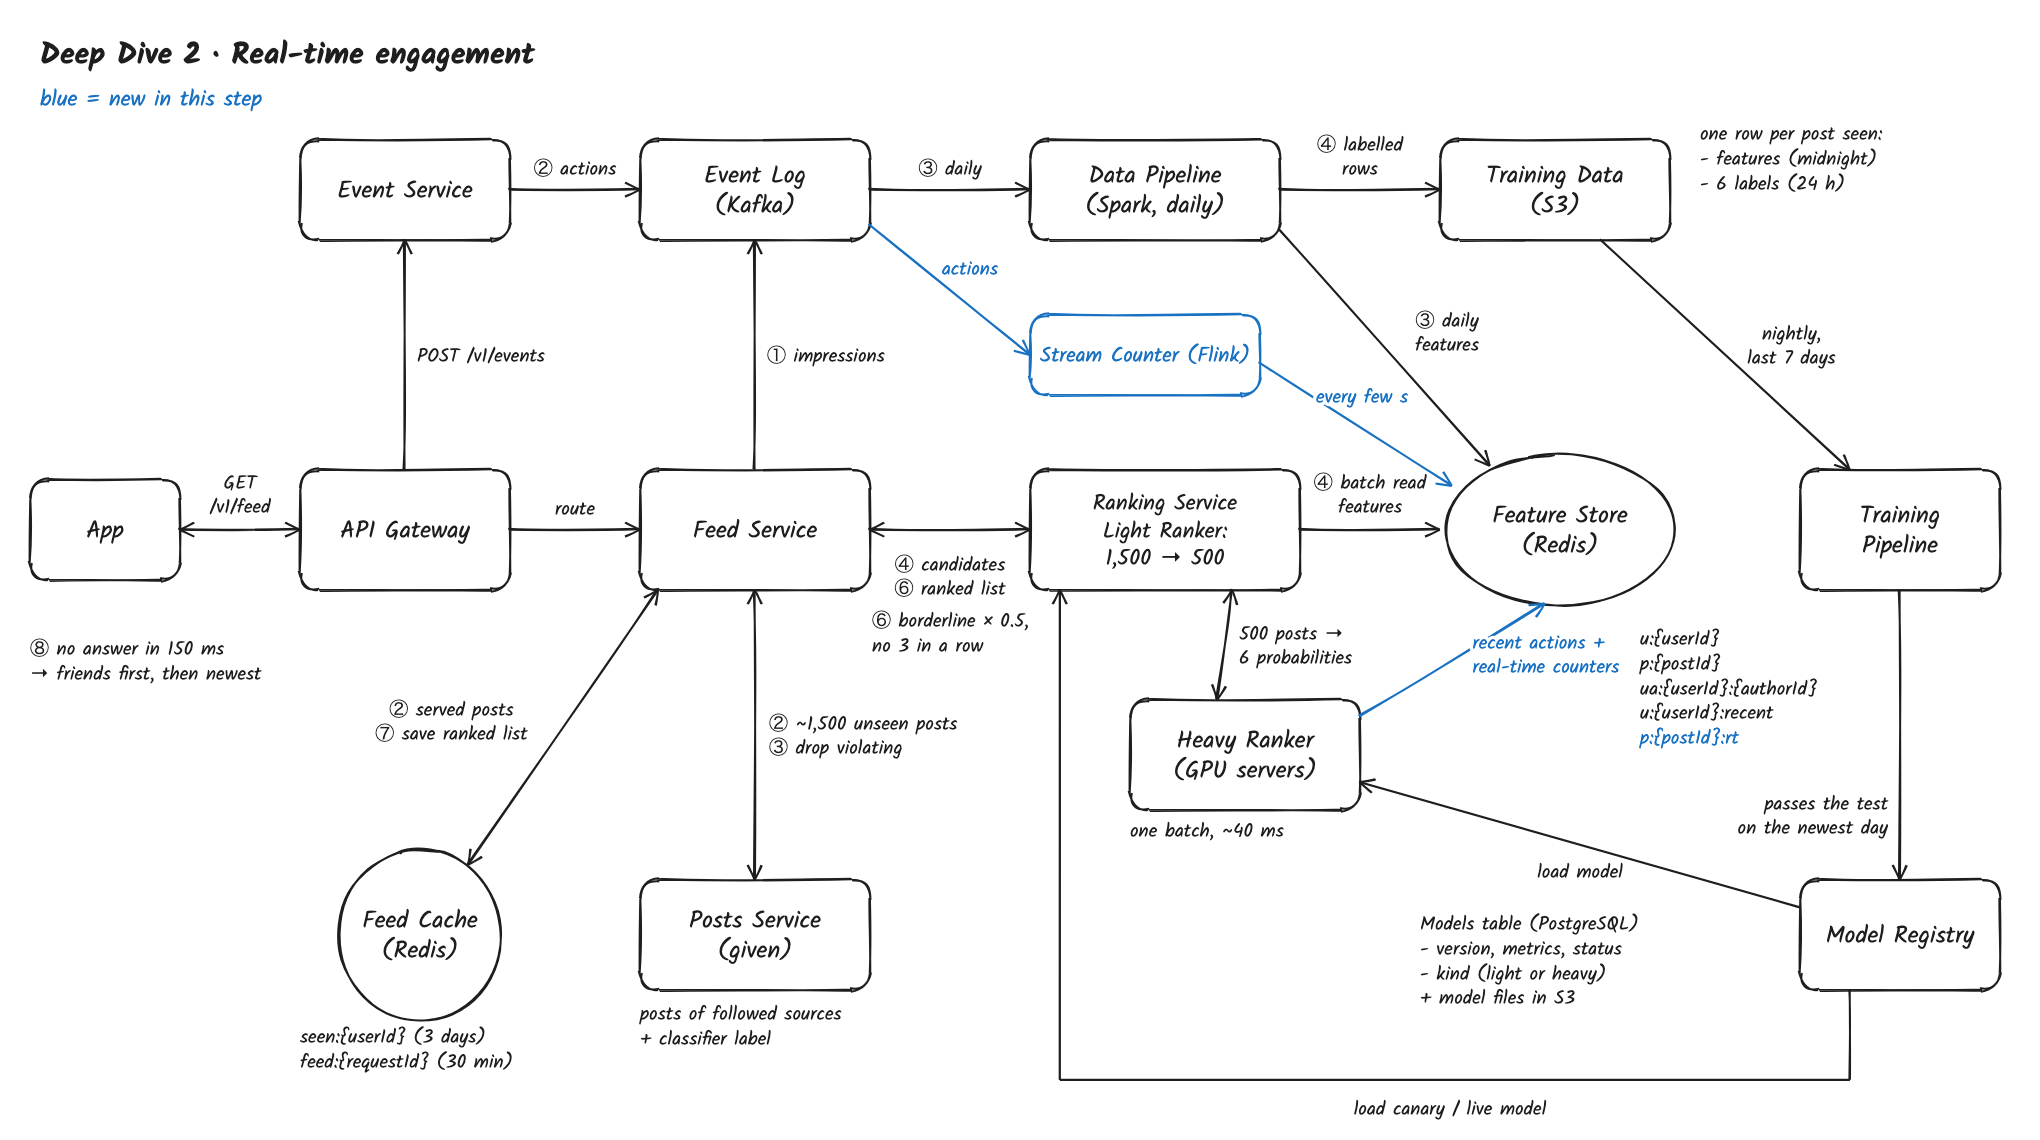
Solution: Count engagement as it happens – a Stream Counter (Flink) reads action events from the Event Log, keeps each post's likes, comments and shares for the last 10 and 60 minutes, and writes them to the Feature Store every few seconds, so a post taking off moves up within a minute or two and the ranker sees what the user just did.
Flink is a stream processing framework: it runs continuously, reads events from Kafka, keeps running counts per key over time windows, and recovers its counts from checkpoints if a server fails.
Feature Store (Redis), written by the Stream Counter
key:     p:{postId}:rt                         hash
fields:  likes10m, comments10m, shares10m, likes60m, comments60m, shares60m, updatedAt
expires: 3 days after the last update

key:     u:{userId}:recent                     list, newest first, trimmed to 50
values:  action, postId, authorId, groupId, time
expires: 7 days- The Stream Counter reads every action event from the Event Log and groups them by
postId. It counts in 1-minute buckets per post and adds up the last 10 and the last 60 buckets. - It writes a post's counters to
p:{postId}:rtat most once every 10 seconds, and only for posts whose counts changed. Load: about 200B posts seen a day with a few percent getting an action is about 6B actions a day, roughly 70K a second on average and 200K at peak, which a few dozen Flink servers handle; the Feature Store gets far fewer writes than that. - A viral post can get 50K comments a second, all for one key. Each Flink server first adds up its own share for one second and sends one partial count, so a hot post costs a few updates a second instead of 50K.
- For each action, the Stream Counter also pushes it onto the user's
u:{userId}:recentlist. The Heavy Ranker already reads this list (deep dive 1), so a page the user hid this morning ranks lower at their next open. - The Heavy Ranker reads
p:{postId}:rtfor its 500 posts in the same batch call as the other features, with the post's age. A brand-new post has no counts yet, so the author's average engagement per post (daily) stands in for it until counts arrive. - If the Stream Counter falls behind, ranking keeps working with the last counts it wrote; an alert fires when they are more than 5 minutes old.
- The model can only learn what these counters mean if training sees the values the ranker saw at the time; deep dive 3 does that.
Other options:
- Run the Data Pipeline every hour – an hour is still 12 times the 5-minute target, and recomputing every feature every hour costs far more than counting only what changed.
- Count at request time from the Event Log – reading every recent event of 500 posts for each of 300K requests a second is impossible within the budget.
- Retrain the model every few minutes – a fresher model, but it doesn't help this post: its own counts change faster than any model can be retrained.
Trade-off: two pipelines now compute engagement, the daily one and the streaming one; if they count differently, the model sees one feature with two meanings, so both use the same event definitions and are compared daily.
What changed: the Stream Counter is new; the Feature Store gets p:{postId}:rt and u:{userId}:recent, now updated in seconds; the Heavy Ranker reads them. NFR 3 is met.
3. How do we train on what users did without learning from features they never had, or from where we put the post?
The problem: the Data Pipeline joins each impression with features computed at midnight, so a post served at 8:00 with 3 comments is trained as if it had its end-of-day 300; the model learns from the future, and the real-time counters from deep dive 2 never appear in training at all. Posts in the top slot also get several times more actions than the 10th just for being first, so the model learns "what we put first gets engagement" and repeats its own choices. And about 95% of the 200B rows a day have no action, which mostly costs training time (Label, FR 4).
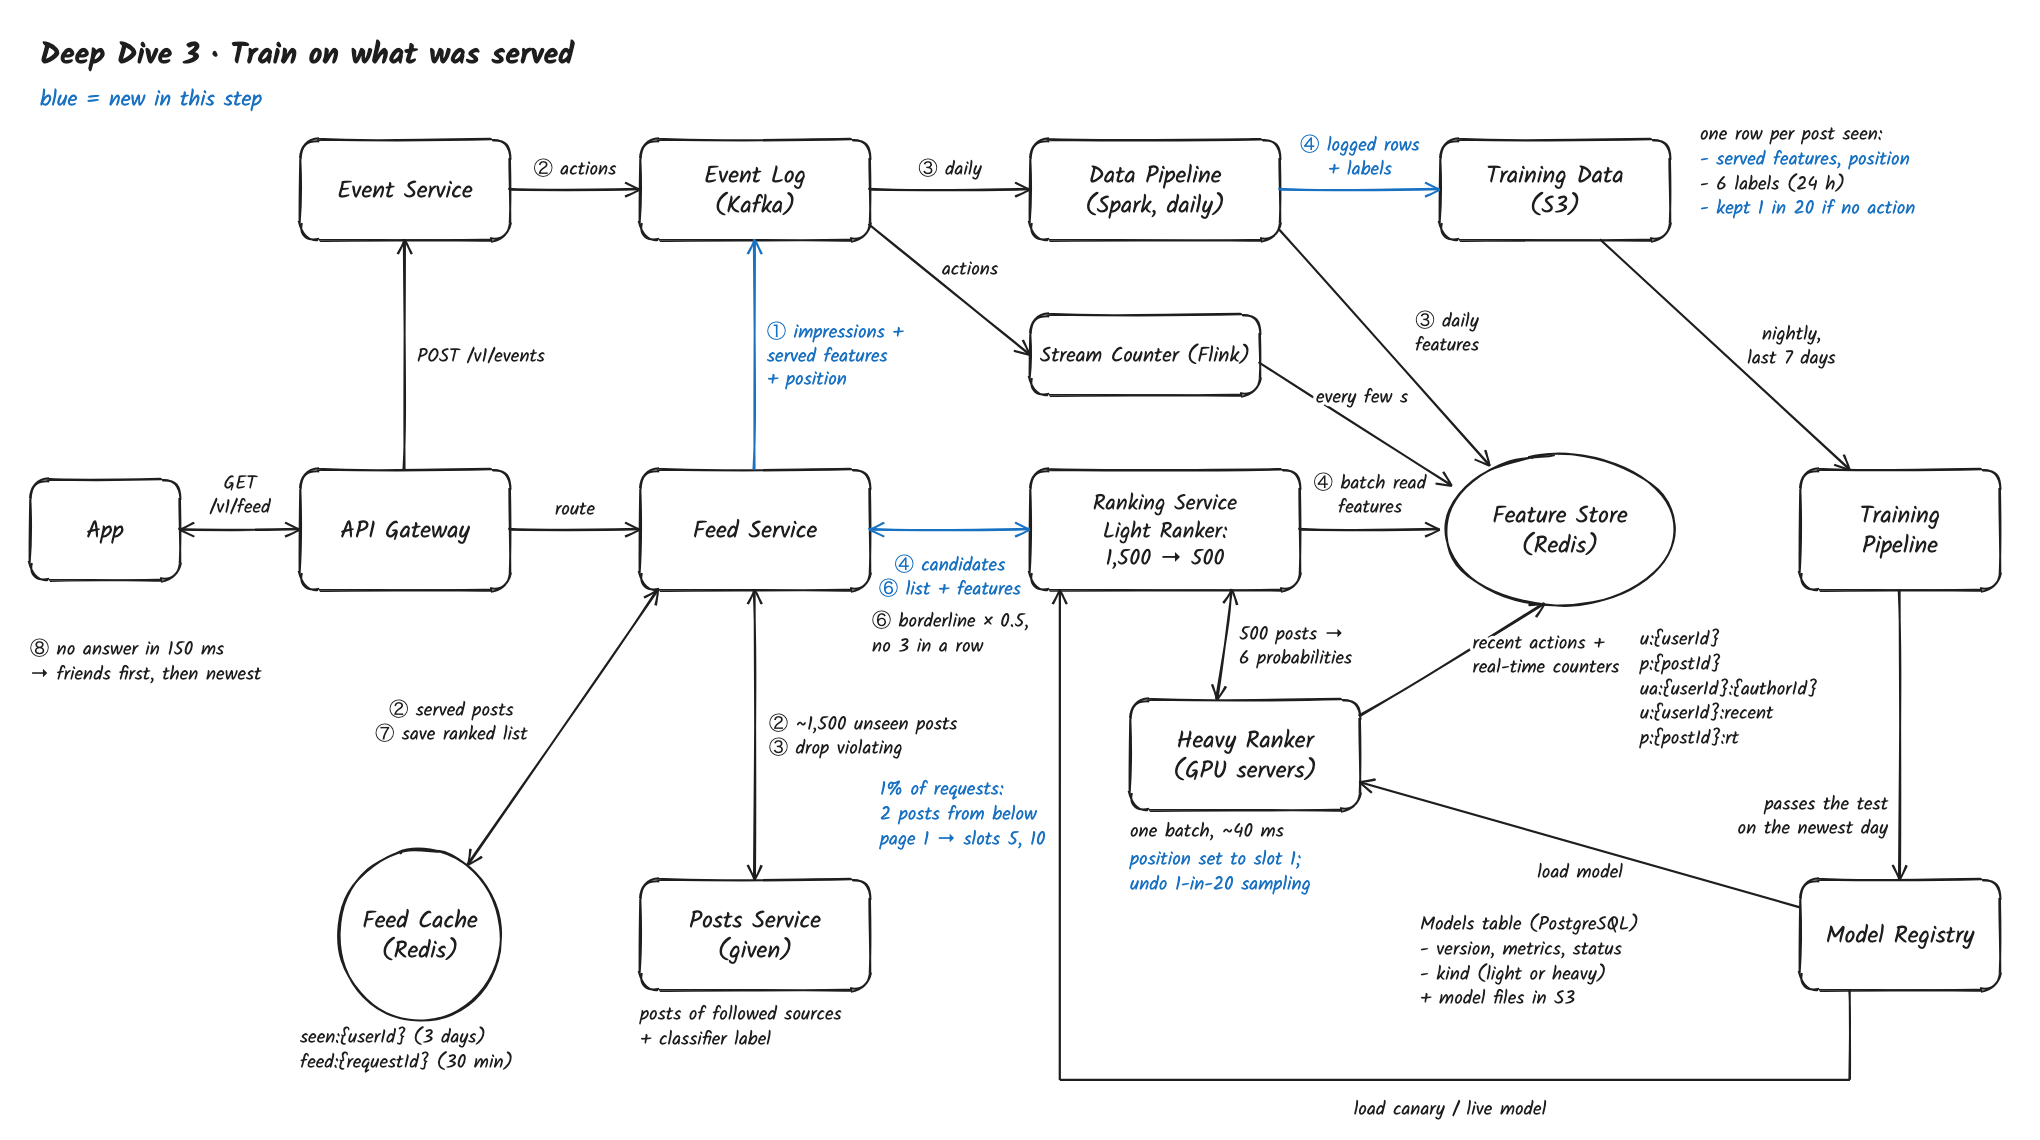
Solution: Train on exactly what was served – the Ranking Service returns the features it used for each post on the page, the Feed Service logs them with the post's position in the impression event, and the Data Pipeline labels those logged rows, keeping every row with an action and 1 in 20 of the rest, so training matches serving and the model learns a post's value rather than its slot.
- With each page, the Ranking Service returns the features the Heavy Ranker used for those 10 posts (real-time counters included), and the Feed Service writes them into each impression event in the Event Log, about 0.5 KB per post. Load: 200B posts seen a day × 0.5 KB is about 100 TB a day, which the Event Log keeps only 2 days, until the Data Pipeline has labelled them.
- The Data Pipeline no longer adds features: for each impression with a
viewevent, it joins the user's actions within 24 hours to the logged row, so each row holds exactly what the ranker saw at that moment. - Sampling: it keeps every row with at least one action and 1 in 20 of the rows without, about 20B rows a day instead of 200B. Each row stores the rate it was kept at.
- Correcting for sampling: a model trained on this data overestimates every probability, because 19 of every 20 "nothing happened" rows are gone. The Heavy Ranker converts each prediction back before calibration: the true probability is the prediction divided by (the prediction plus 20 times one minus the prediction).
- Position: the slot each post was shown in is a training feature, so the model learns how much the slot itself adds. At serving, the Heavy Ranker sets it to slot 1 for every post, so scores compare posts as if each were shown at the top.
- Exploration: in 1% of requests the Ranking Service puts two posts the Light Ranker kept, but the Heavy Ranker placed below the first page, into slots 5 and 10. Their logged rows give labels for posts the model would never have shown, so it doesn't only learn from its own choices.
- A new feature can only be trained on once it has been logged for a week; until then, it is rebuilt for past rows from the Event Log as of each impression's time.
Other options:
- Rebuild features as of each impression's time (a point-in-time join) – correct for the daily features, but rebuilding minute-level counters for 200B rows a day means running the streaming job again over history; logging them once is simpler.
- Decide the sample at serving time and log only those rows – far less data, but nobody knows at serving time which posts will get a share or a report, so the rarest labels would lose 19 of every 20 examples.
- Weight each row by how likely its slot is to be noticed – removes position bias in theory, but the weights must be measured with randomized feeds and are very noisy for low slots.
Trade-off: about 100 TB a day of extra logs, and every new feature waits for logged history or a rebuild before the model can use it.
What changed: impression events carry the served features and position; the Data Pipeline joins actions to logged rows and samples them; the Heavy Ranker learns from position and corrects for sampling; 1% of requests explore. FR 4 is met as intended: each new model learns from what users really saw.
What's Expected at Each Level
Mid
- Makes all three flows work end to end: candidates from the Posts Service, a baseline model on features from the Feature Store, cached pages, events in a log, a nightly model with an offline check.
- Frames the problem with more than one label: predicts comments, shares, hides and reports, not only clicks, and names a fallback when ranking fails.
- Reaches deep dive 1 with hints, and suggests a cheaper first stage once told the strong model can't score 1,500 posts per request.
Senior
- Does the math without hints: 300K requests a second × 1,500 posts is 450M scores a second, so a strong model only fits after a cheap first stage, and sets a budget for each stage.
- Designs the multi-task Heavy Ranker with calibrated heads, and explains why the value score needs calibrated probabilities and why the offline metric is log loss, not only AUC.
- Spots that daily features miss posts taking off and adds streaming counters with a fallback for new posts.
- Reaches deep dive 3: logs the served features so training matches serving.
Staff
- Names the objective as the core decision early: what the value weights reward changes what people post, so weights change only through long A/B tests with hides, reports and daily users as guardrails.
- Raises failures before being asked: Heavy Ranker timeout falls back to the Light Ranker, a lagging Stream Counter keeps the last counts, a failed nightly model is never shown to users.
- Handles the feedback loop: position as a feature set to the top slot at serving, a small exploration share, and sampling with its correction.
- Owns the cost: 1,500 GPU servers instead of 4,500, a viral post pre-aggregated, 100 TB a day of logs kept only until labelled.